Work Wharton Research Data Services
Text analytics that survived contact with production
An NLP pipeline over SEC filings, news, social media and earnings transcripts. Half of an award-winning system.
- Client
- Wharton Research Data Services
- Role
- Developer
- Period
- 2019 to 2023
- Focus
- Development, NLP, Machine Learning
- Future Edge 50 2021 award winner
- 4 data products connected
- Grid scheduled batch NLP
Research teams needed to run natural language processing over financial text at a scale their laptops could not touch. I built the application that let them do it.
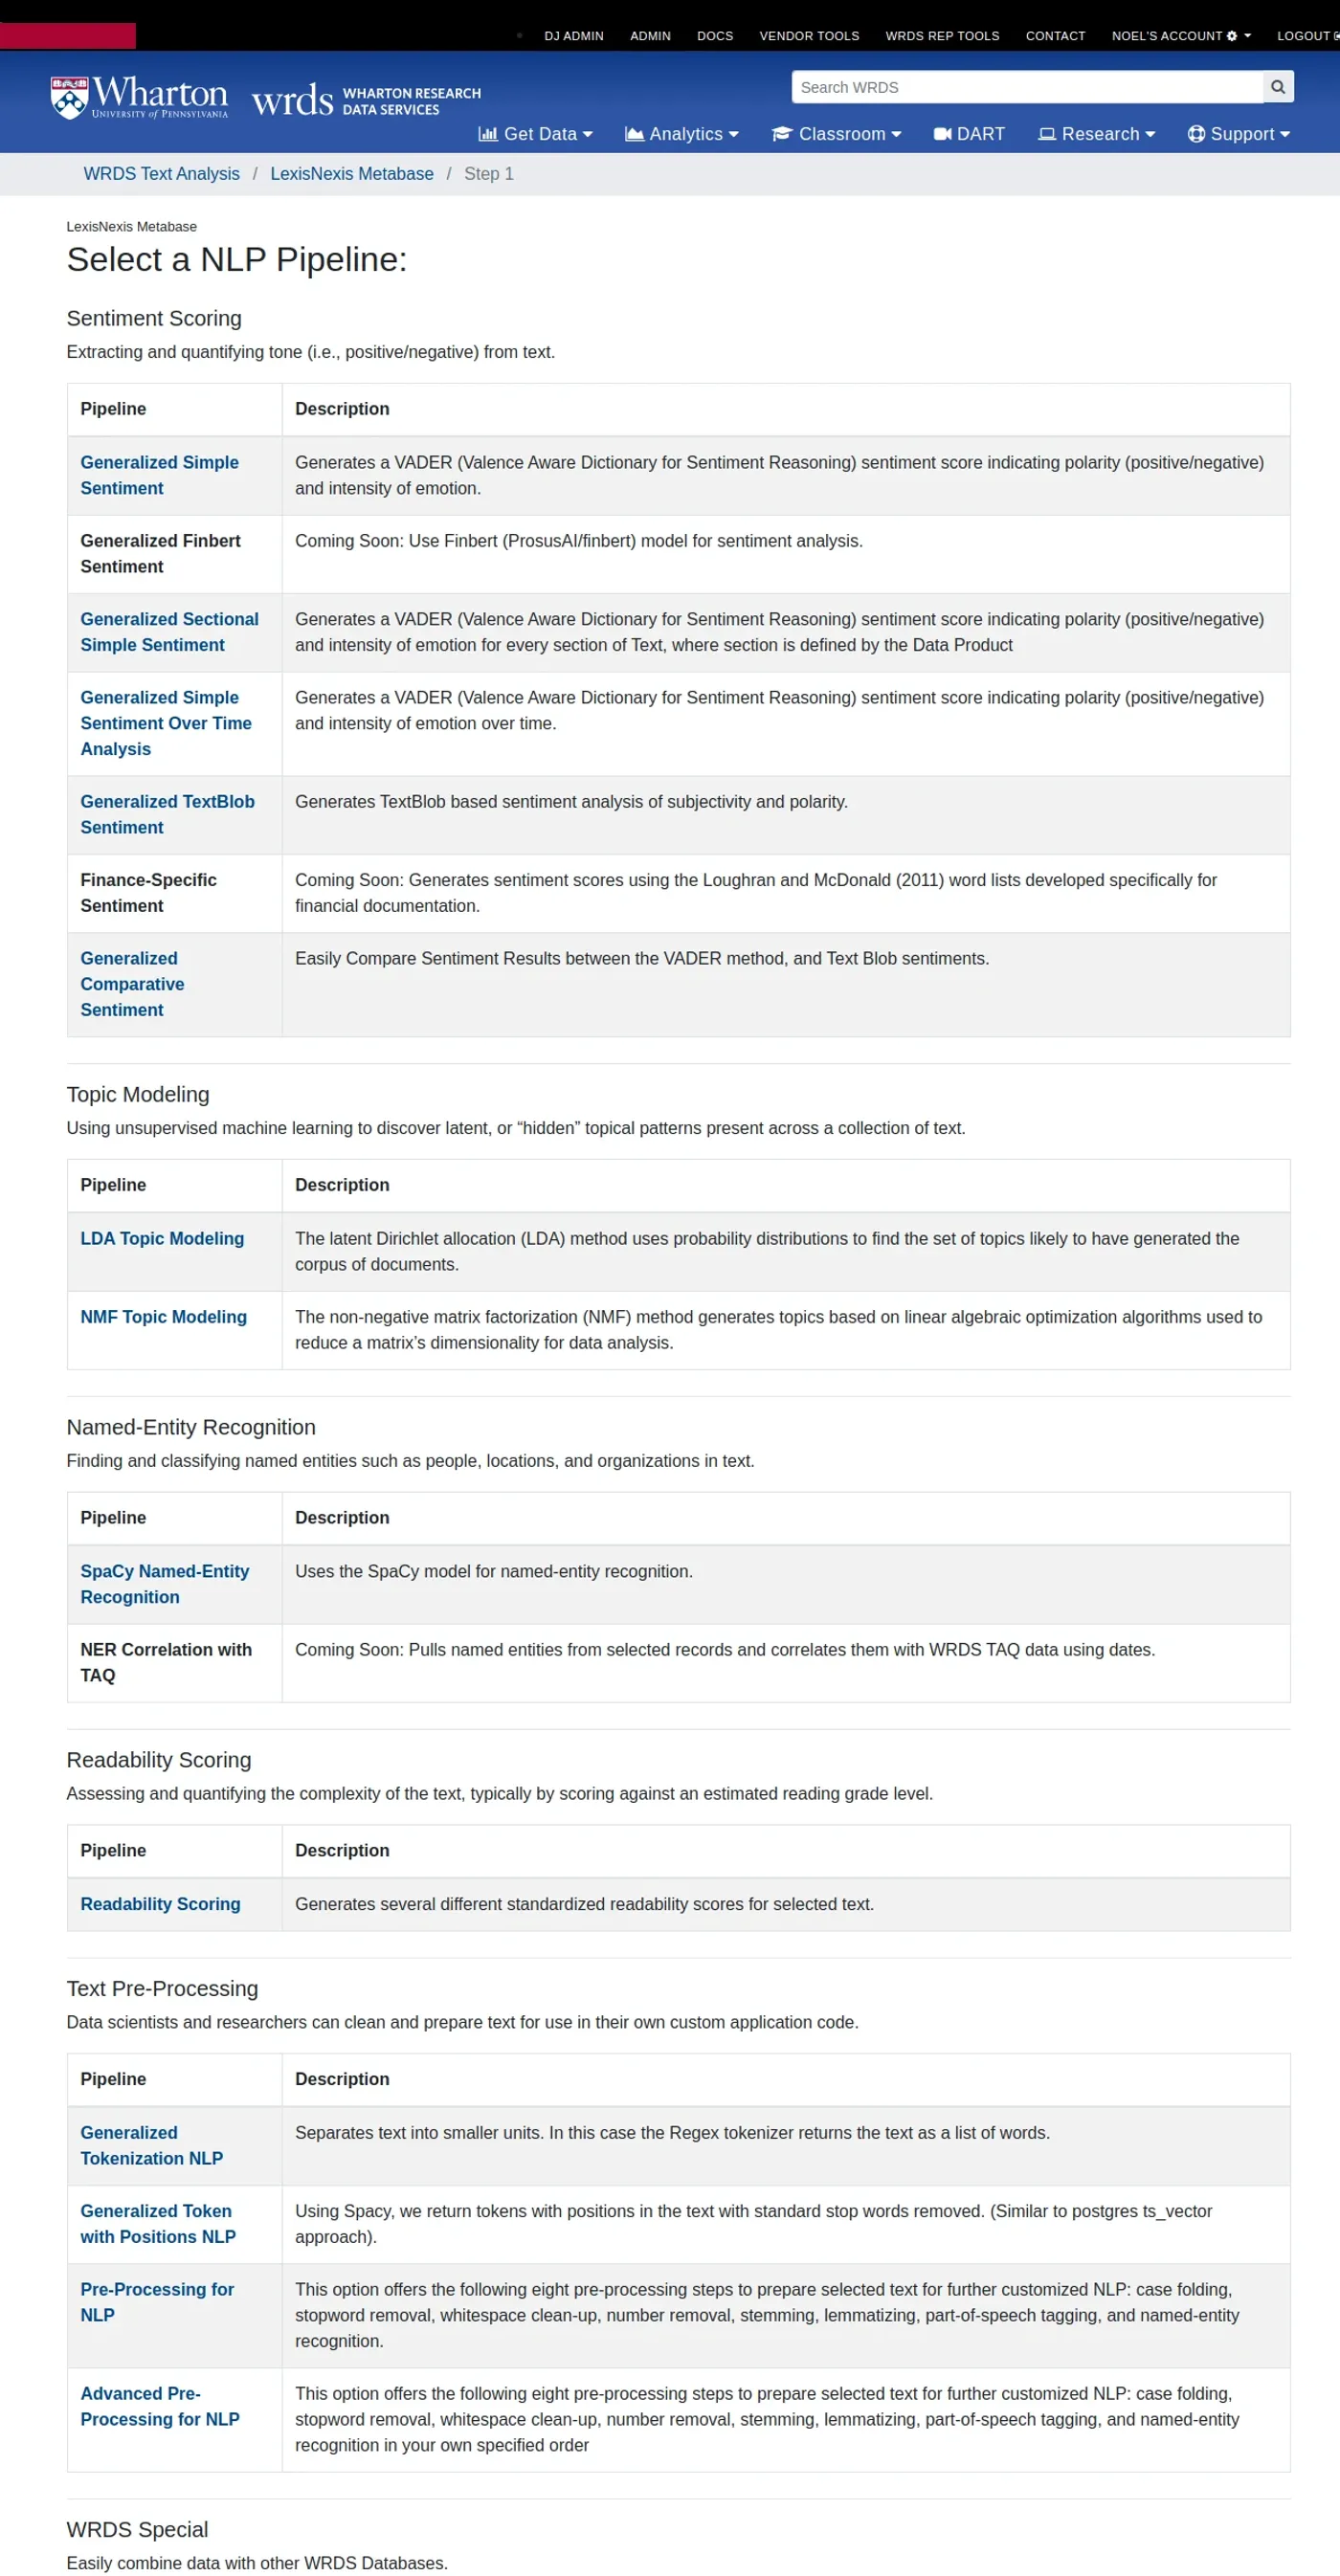
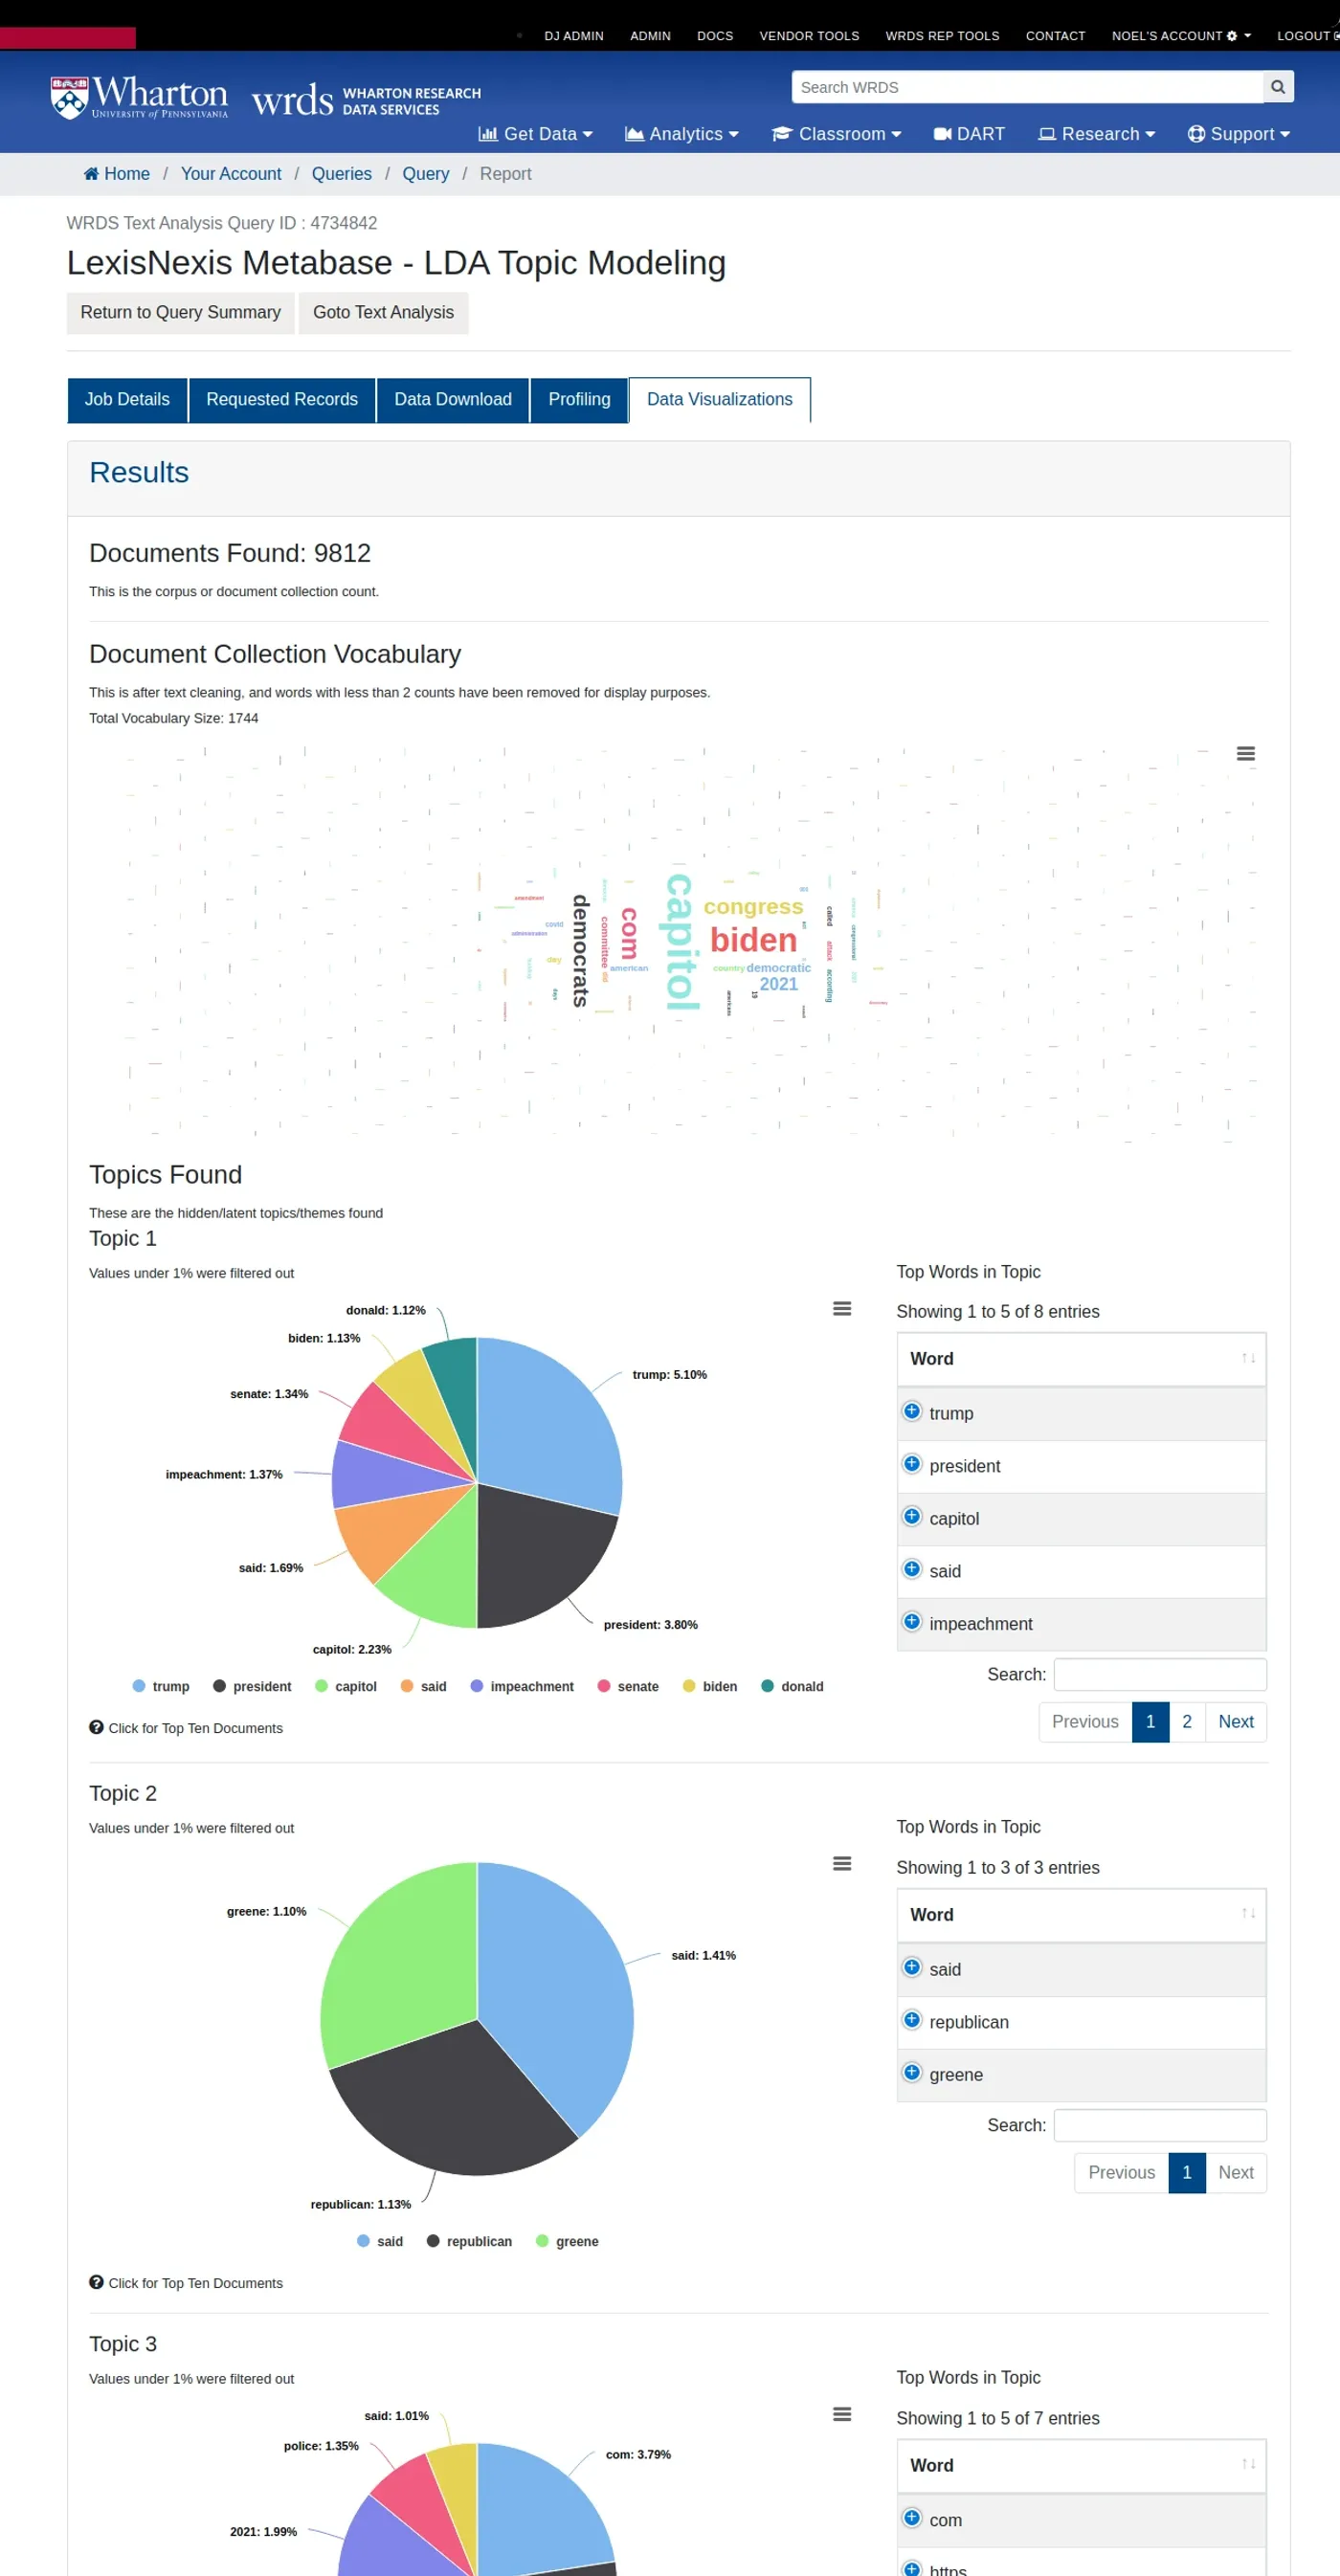
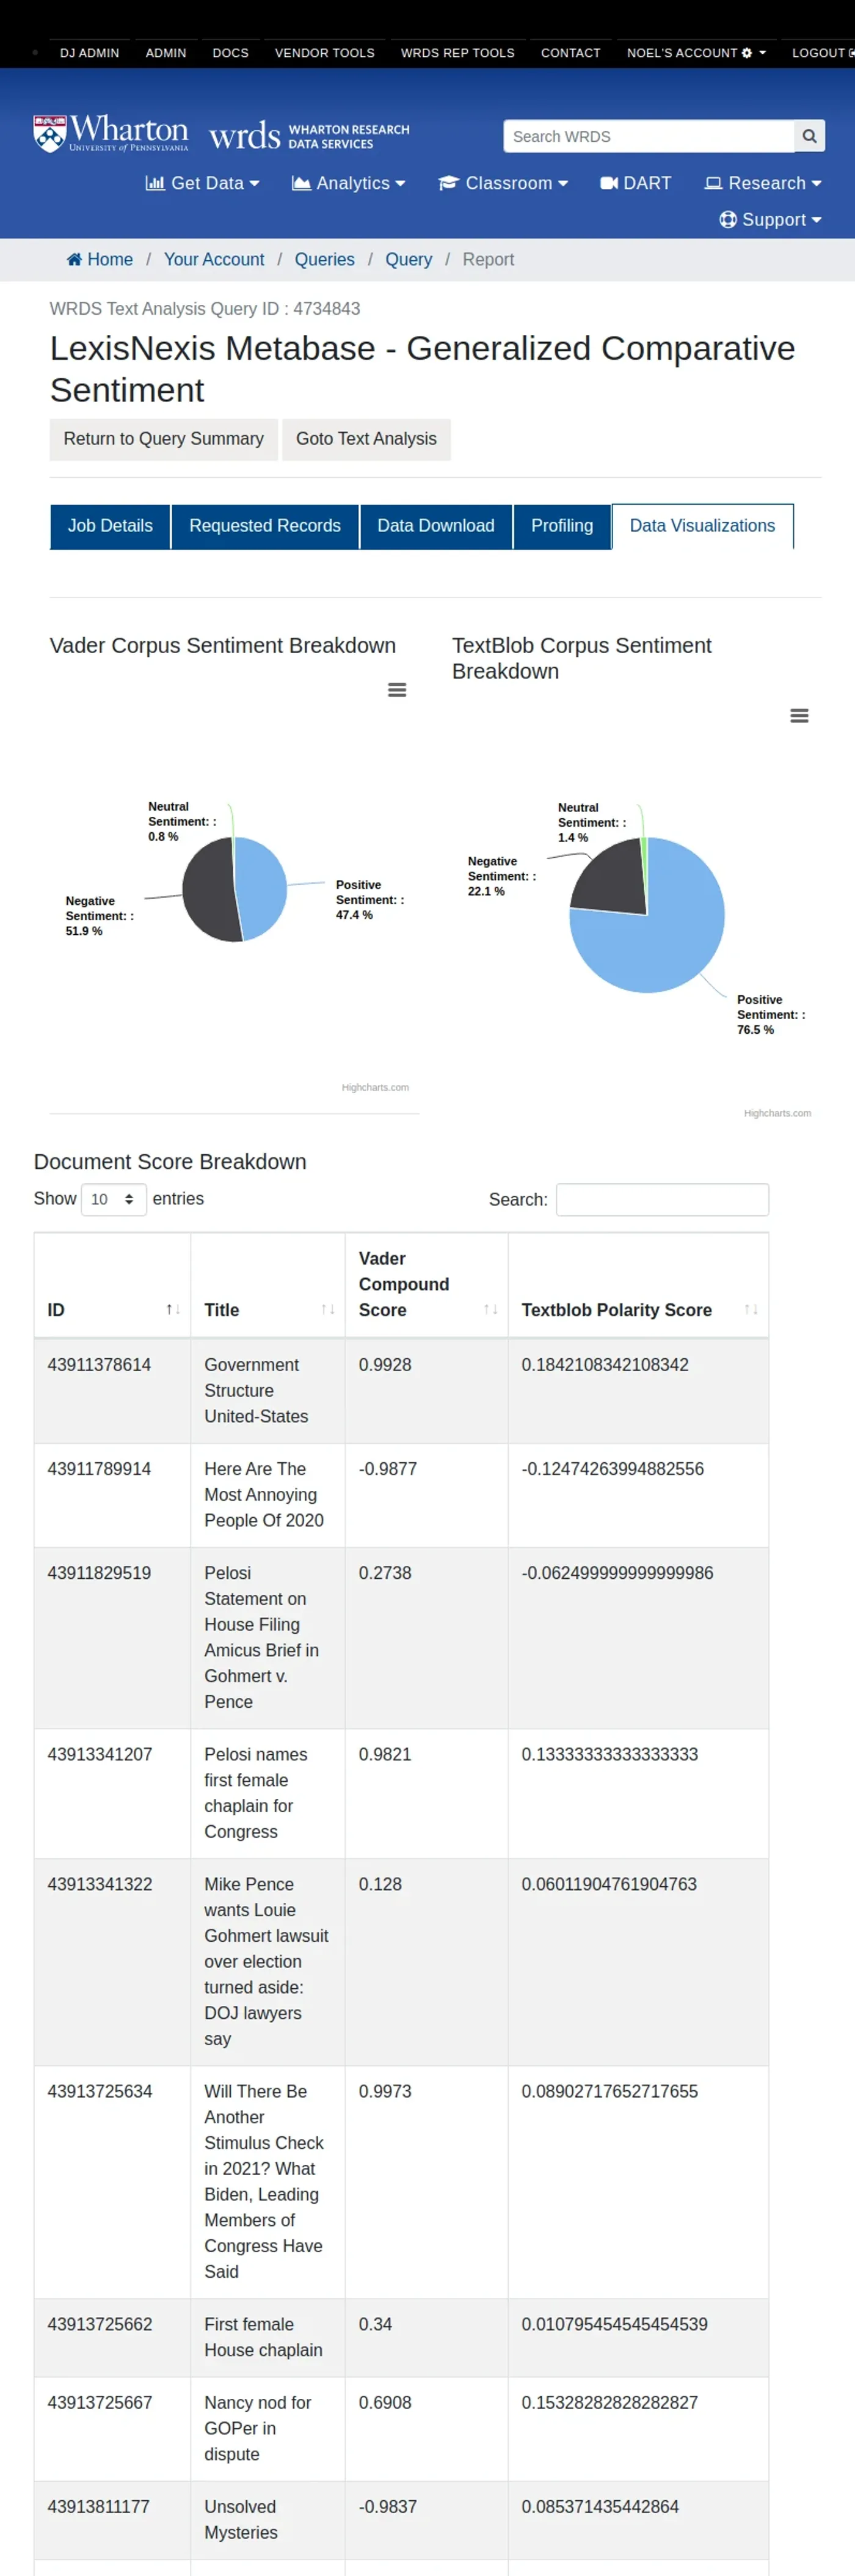
Users search and select documents into a cart. The cart feeds a set of industrialized NLP pipelines scheduled on the Univa Grid Engine. Results come back as reports in the web application. News, social media, SEC filings and company transcripts all flow through the same path.
The hard part was not the models
Getting a pipeline to run on a researcher’s sample is easy. Getting it to run unattended against a full corpus without hitting CPU and memory ceilings is the actual job. I rewrote major sections of several pipelines to stream through SQLite instead of holding state in memory, which is what made them safe to run at full size.
This application is one half of the WRDS Text Analysis System, which won a 2021 Future Edge 50 award. Text Search is the other half.
Screens